Web Scraping Without Getting Blocked: A Complete Guide (2026)
Web scraping in 2026 is an arms race. Websites deploy increasingly sophisticated anti-bot systems, while scrapers develop new techniques to appear human. This guide covers everything you need to know to scrape reliably without getting blocked.
Understanding Anti-Bot Defenses
Modern websites use multiple layers of protection. Understanding each layer helps you build a strategy that addresses all of them.
Layer 1: Rate Limiting
The simplest defense. If you make 100 requests per second from one IP, you’re obviously not human. Limits vary from site to site and are rarely published. As a rough guide:
- Strict: large platforms and search engines
- Moderate: most e-commerce sites
- Relaxed: static content sites
Start slow, and back off as soon as you see “Too Many Requests” errors or CAPTCHAs.
Layer 2: IP Reputation
Anti-bot services keep reputation data on IP addresses. Datacenter IPs (AWS, GCP, DigitalOcean) are easy to recognize and often treated with suspicion, while residential IPs look like ordinary home connections and usually get more trust.
| IP Type | Trust Level | Speed |
|---|---|---|
| Datacenter | ❌ Low | Fast |
| Residential | ✅ High | Variable |
| Mobile | ✅ Very High | Slow |
| ISP (Static Residential) | ✅ High | Fast |
Datacenter IPs are usually the cheapest and mobile IPs the most expensive. Prices vary between providers and change often, so compare current plans.
Layer 3: Browser Fingerprinting
This is where many scrapers get caught. Even with rotating IPs and realistic headers, websites can detect automation through:
- Navigator properties — Headless Chrome has telltale differences (
navigator.webdriver = true) - Canvas/WebGL rendering — Identical fingerprints across requests = detected
- JavaScript execution — Bots don’t scroll, don’t move the mouse, don’t trigger hover events
- TLS fingerprint (JA3/JA4) — The SSL handshake itself reveals the client type
- HTTP/2 fingerprint — Frame ordering and settings differ between real browsers and HTTP libraries
Layer 4: Behavioral Analysis
The most sophisticated layer. Detection systems look at:
- Click patterns (too regular = bot)
- Page navigation flow (going directly to product pages without browsing = suspicious)
- Session duration (too short or too long)
- Interaction timing (humans have natural variance; bots don’t)
The Anti-Bot Ecosystem
Services you are likely to run into include Cloudflare, Akamai Bot Manager, PerimeterX (HUMAN), DataDome, reCAPTCHA v3 and hCaptcha. How strict any of them is depends on the service and on how each site configures it, so test against the sites you actually target.
Proven Techniques for Unblocked Scraping
1. Use Real Browsers, Not HTTP Libraries
The single most impactful change you can make. Tools like requests (Python) or axios (Node.js) send HTTP requests that look nothing like a real browser.
Instead, use:
- Playwright — Microsoft’s browser automation library
- Puppeteer — Google’s Chrome automation
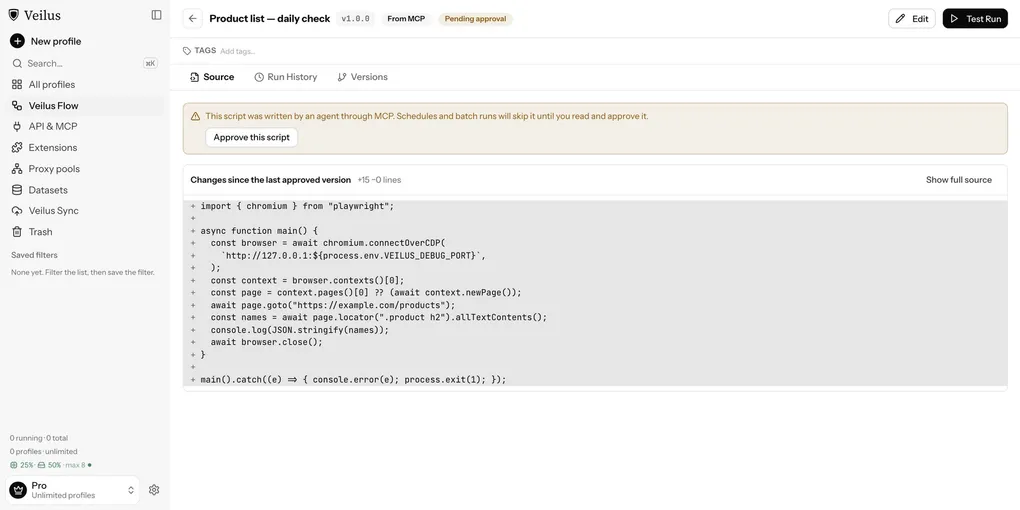
- Veilus + Veilus Flow — Playwright scripts written by your AI assistant over MCP, run across profiles with their own fingerprints
// Bad: HTTP library (easily detected)
const response = await fetch('https://target.com/products');

// Good: Real browser (much harder to detect)
const browser = await playwright.chromium.launch();
const page = await browser.newPage();
await page.goto('https://target.com/products');
const data = await page.content();
2. Rotate Fingerprints, Not Just IPs
Many scrapers rotate proxies but use the same browser fingerprint for every request. This is like wearing the same unique outfit to every store while changing your car — the stores still recognize you.
Each scraping session needs:
- A unique canvas fingerprint
- Matching WebGL parameters
- Consistent navigator properties (don’t mix Windows UA with Mac fonts)
- Realistic screen resolution for the supposed device
This is exactly what anti-detect browsers like Veilus do — each profile gets a unique, internally consistent fingerprint.
3. Use Residential Proxies on Protected Sites
On sites with serious anti-bot protection, datacenter IPs tend to be flagged quickly. Residential proxies are the safer choice there.
Choosing a provider: compare where their IPs are located, how they bill, whether they offer sticky sessions, and how they source their residential IPs.
Pro tip: Use sticky sessions (same IP for the entire browsing session) rather than rotating on every request. Real users don’t change IP every 30 seconds. In Veilus, a rotating proxy pool has a per-pool session type for exactly this.
4. Mimic Human Behavior
// Bad: Robot-like precision
await page.click('#add-to-cart');
await page.click('#checkout');

// Good: Human-like behavior
await page.mouse.move(randomX(), randomY()); // random movement
await sleep(random(500, 1500)); // natural pause
await page.click('#add-to-cart');
await sleep(random(2000, 4000)); // "thinking" time
await page.scroll(0, random(200, 400)); // scroll like a human
await page.click('#checkout');
Key behaviors to simulate:
- Random delays between actions (800ms-3s for clicks, 2-5s between page loads)
- Mouse movement before clicking (humans don’t teleport the cursor)
- Scrolling through content (don’t jump directly to the target element)
- Page dwell time (spend 10-30 seconds per page, not 0.5 seconds)
5. Manage Cookies and Sessions
Anti-bot systems track session behavior. A session that:
- Has no cookies → suspicious (everyone has cookies)
- Ignores Set-Cookie headers → a strong bot signal
- Never accesses CSS/JS resources → headless browser detection
Solution: Use a real browser profile that maintains cookies, localStorage, and cache across sessions. Anti-detect browsers do this automatically.
6. Handle CAPTCHAs Gracefully
When you do encounter CAPTCHAs:
- Slow down — CAPTCHAs often mean you’ve triggered a threshold
- Switch fingerprint + IP — The current identity is flagged
- Use solving services as a last resort (2Captcha, Anti-Captcha)
- Wait and retry — Some CAPTCHAs are temporary rate-limit responses
Architecture for Scale
For serious scraping operations (10,000+ pages/day):
                    ┌─── Profile 1 (Fingerprint A + Proxy A)
                    │
Job Queue ──────────┼─── Profile 2 (Fingerprint B + Proxy B)
(URLs to scrape)    │
                    ├─── Profile 3 (Fingerprint C + Proxy C)
                    │
                    └─── Profile N (Fingerprint N + Proxy N)
                              │
                              ▼
                        Data Pipeline
                    (clean → store → export)
Key principles:
- Pool management — Rotate profiles after N requests or M minutes
- Error handling — If a profile gets CAPTCHAs, retire it and use a fresh one
- Rate limiting — Self-impose conservative limits per profile, and slow down further when errors or CAPTCHAs appear
- Retry logic — Exponential backoff on failures
Tools We Recommend
| Tool | Use Case | Price |
|---|---|---|
| Veilus | Multi-profile management + automation (scraping recipe) | Free (5 profiles) |
| Playwright | Browser automation scripting; Veilus runs Playwright scripts across profiles (Veilus Flow) | Free |
| A residential proxy provider | Residential proxies | Paid |
| Scrapy | Large-scale structured scraping | Free |
| A CAPTCHA-solving service | CAPTCHA solving (last resort) | Paid |
Common Mistakes
- Using headless mode — Many anti-bot systems detect headless browsers. Use headed mode with a virtual display if needed.
- Ignoring TLS fingerprints — Your JA3 hash reveals the client. Real Chrome has a specific TLS fingerprint that libraries don’t match.
- Same user-agent for all requests — Rotate UAs, but keep them consistent within a session.
- Scraping logged-in pages without session management — Cookies and auth tokens need careful handling.
- Not respecting
robots.txt— It won’t block you technically, but it can have legal implications.
Legal Considerations
Disclaimer: This guide is for educational purposes. Always check the website’s Terms of Service and applicable laws in your jurisdiction. The rules differ between jurisdictions, and scraping behind login walls or ignoring explicit restrictions carries more legal risk than collecting publicly available data.
Need to manage multiple scraping profiles? Try Veilus free — 5 profiles with unique fingerprints, no credit card.